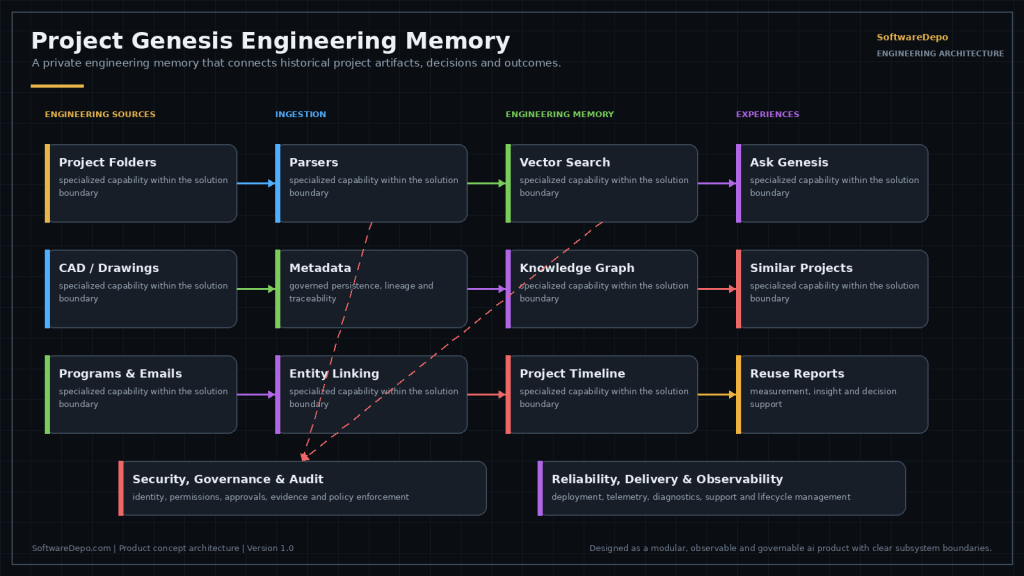
Every established engineering firm is sitting on twenty years of project directories: drawings, proposals, specifications, manuals, PLC and controls programs, bills of material, site photographs, and the email thread where somebody explained why a decision was made. It is the most valuable asset in the business and the least usable, because finding anything in it depends on the person who remembers where it is.
Status: product concept, in active development. This is something we are building, not something you can buy today. We publish our roadmap because the engineering thinking behind it is the useful part — and because we would rather show you the design than imply a finished product.
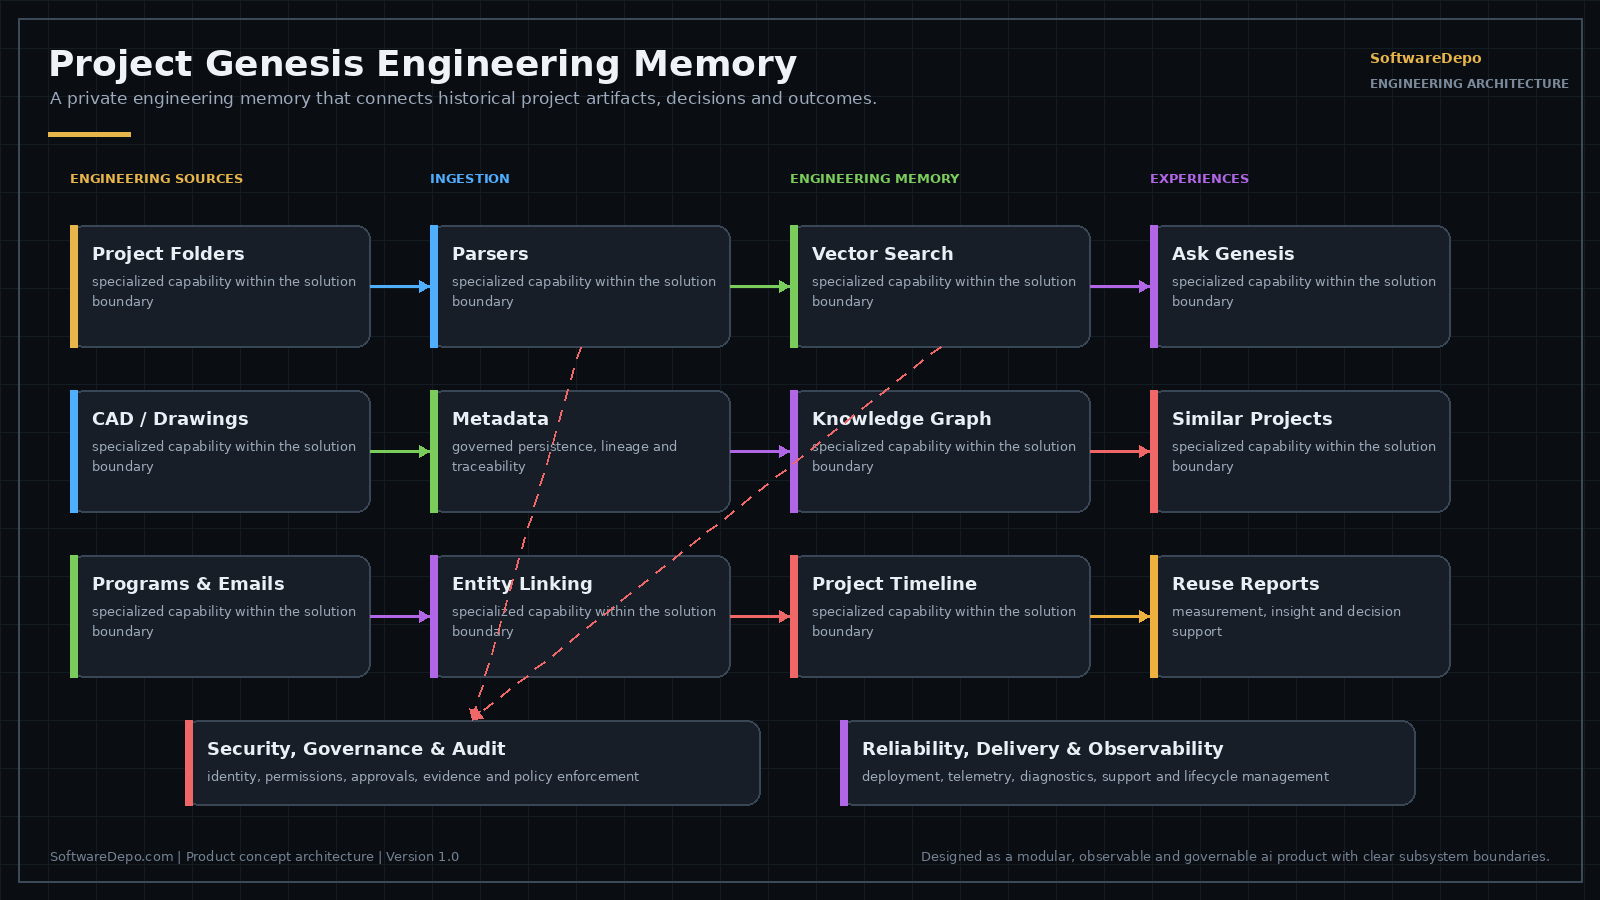
Project Genesis is designed to turn those directories into institutional memory you can query — deployed on-premises or in a private cloud, because this material is not going into anyone else’s system.
What It Is Designed To Do
- Project-directory ingestion — point it at the archive as it actually exists, rather than requiring a migration project first.
- Drawing, document and code extraction — read the content, not just the filenames.
- Entity and relationship indexing — connect projects, equipment, customers and components to each other.
- Engineering semantic search — ask in engineering terms rather than guessing folder names.
- Project similarity and reuse analysis — find the job you already did that resembles the one being quoted.
- Component obsolescence tracking — know which installed base depends on a part going end-of-life.
- Commissioning lessons and issue history — surface what went wrong last time, before it goes wrong again.
- Cited answers and provenance graph — every answer points back to the document it came from.
Why Citations Are the Whole Point
An engineering answer you cannot trace is not usable. If the system says a previous installation used a particular controller, an engineer needs the drawing that says so — not a confident paragraph. Provenance is what makes this a reference tool rather than a plausible-sounding risk, and it is the same retrieval-grounded approach we apply to enterprise knowledge generally.
Tell us if this matches a problem you have — early input shapes what we build first, and we will give you an honest view of where it stands.
Why Engineering Archives Resist Ordinary Search
An archive is not hard to search because it is large. It is hard to search because what an engineer needs is rarely in the text of any single file. A drawing carries its meaning in geometry, title block and revision marks. A controls program carries it in tag names, comments and the naming habits of whoever wrote it. A bill of material carries it in part numbers that mean something only against a catalog. Full text search over those files returns filename matches and boilerplate, because that is the only text it can see.
The second problem is identity. The same pump is a tag on a drawing, a line item on a bill of material, a symbol in a controls program and a phrase in a service email, and none of those strings match each other. The same site is a customer name in one folder and a job number in another. Answering which jobs used a particular actuator is an entity resolution problem before it is a search problem, and that is the part a generic search tool hands back to the reader.
The third is that some of the reasoning was never written as a document. A line like we moved it to the north riser is complete to the two people on the thread and meaningless to everyone else, because it assumes the equipment, the job and the week. Recovering that is less about parsing text and more about attaching an informal statement to the entity and project it refers to, which is why the index has to be built around entities rather than around files.
When A Simpler Answer Is Better
Retrieval over an archive is worth building when the questions are historical and the archive is the only place the answer exists. Several situations fail one of those tests, and in those cases the honest recommendation is a smaller fix.
A useful test before any of this: write down the questions you most want answered, and mark the ones a filename, a folder path or a date could answer on its own. If most of them can be, the problem is naming discipline and the cheaper fix is the right one. The questions that justify this kind of work are the ones that need the content of a drawing or a program, compared across projects, with a source you can open and read.
- The archive already sits in a PDM or document management system with enforced check in, controlled revisions and metadata people actually populate. Structured metadata answers a large share of these questions directly, and a semantic layer on top is a smaller gain than it looks.
- The questions are about active work rather than history. Not knowing the current revision of a live job is a process problem upstream of any index, and indexing it will not create a discipline that does not exist.
- The archive is small enough, or recent enough, that two or three people can navigate it reliably and the firm is not exposed if one of them leaves.
- The contents are not trusted. If drawings are known to be wrong because as builts were never returned, retrieval makes the wrong answer faster to find. That correction has to happen in the files first.
- The real requirement is a retention record or a legal hold. That is records management, with retention rules and audit obligations, and it should be solved with a records system rather than a search layer.
Failure Modes The Design Has To Handle
Citations settle whether an answer can be checked. They do not settle whether it is current. A citation pointing at a superseded drawing is precise and wrong, so revision status has to be something the system reads and reports rather than something it infers from a folder name. Where status is genuinely ambiguous, the intent is to return the competing candidates and say why they conflict instead of picking one quietly.
Entity collapse is the second failure. Two sites called Building 3, two projects under the same customer name in different years, a part number reused for a different component after a vendor change: merging any of those produces answers that are confident and about the wrong thing. Merging is designed to be conservative, splitting where the evidence is thin and leaving a reviewable list rather than an invisible decision.
Extraction quality varies by file, not by archive. Vector CAD, native PDF and text based controls exports come out clean. A scanned sheet, a photograph of a panel, a handwritten markup: those depend on OCR and are where plausible misreadings come from. The design carries extraction confidence forward into the citation, so a weak source shows up in the answer rather than being averaged into it.
Frequently Asked Questions
What is Project Genesis, concretely, and what is it not?
It is not a document management system and is not intended to replace one. It does not move, rename, reorganize or take custody of anything: it builds an index beside the archive, and your file server stays the system of record. It is also not a general purpose chat tool aimed at a folder, because the unit being indexed is the engineering entity and its relationships, not a page of text. As a product concept still in development, what exists today is the design and the roadmap, not a system you can stand up.
Can we buy it, pilot it, or see it running somewhere?
No. It is in active development, there is no release date to give you, and there are no existing installations to point at. What is available now is the design itself: the ingestion approach, the indexing model and the constraints described on this page, and a conversation about whether they hold against your archive. If your situation breaks an assumption in that design, that is worth knowing before code gets written against it.
What does it run on, and what has to already exist on our side?
Read access to the archive where it already sits, an identity source it can inherit permissions from, and compute inside your environment for the extraction pass. The files can stay on a Windows file server, a NAS, a network share or a document library, because the design assumes they stay where your teams already use them. The identity source matters because permissions are meant to follow your existing groups rather than a second access model somebody maintains by hand. No cleanup project or metadata tagging effort is a precondition either.
How is the rollout designed to proceed, in order?
First a census: an inventory of the archive by file type, volume, age and duplication, with no content extraction at all. That census is meant to be the input to the scope discussion, which is why it is the first step rather than a byproduct of indexing. Extraction follows by file type, starting with the formats that come out cleanly, so there is something testable before the difficult material is queued. Then entity resolution, with the resulting list of projects, customers, equipment and components reviewed by someone who knows the work. Then validation: ask questions whose answers you already know, and check the citations rather than the prose.
How is it designed to integrate with the systems we already run?
Through read only connectors keyed on whatever identifier already ties your records together, typically the job or project number if you have one. The intent is that ERP or accounting supplies the job record, the CRM supplies the customer, a service or ticketing system supplies issue history, and the archive supplies the documents behind all of it, with none of those systems changing to accommodate it. The index is also meant to be reachable by other software through an MCP style server interface rather than only a web page, so an internal application or an agent can query it under the same permissions a person has. Nothing is designed to write back into those systems.
Where would the data live, and what stays under our control?
The design keeps the archive where it is and puts the deployment inside your boundary, on-premises or in a private cloud. Access boundaries are meant to be inherited from your existing groups rather than invented by the system, so an answer should not surface a document the person asking could not already open. Indexes and extracted content are derived from your files, and taking a directory out of scope is designed to remove what was derived from it. Ownership, retention and deletion terms belong in a written agreement rather than a claim on a web page, and we would expect them settled before anything is indexed.
What do we have to provide or decide?
Three decisions, and software cannot make any of them for you. The scope boundary: which directories are in, which are excluded, and what happens to material that probably should not have been retained. Revision authority: which of several near identical drawings is the issued one, whether a folder marked old is superseded or simply relocated, and who settles it when the archive disagrees with itself. The entity vocabulary: whether a project means a job number, a site or a contract, because that choice determines how everything else joins. What you provide is access, a point of contact who knows the folder conventions, and time from someone who can review the entity list.
How is the index meant to stay current after the first pass?
By incremental re-crawl. New and changed files get picked up on a schedule so only the delta is extracted, which is a smaller and more predictable load than the first pass. The index is designed as a derived artifact, which means it can be rebuilt from the source files when extraction logic improves or when something was indexed wrong. That also keeps the archive as the thing you maintain: if a project directory gets reorganized, the index follows the files rather than the other way around.