
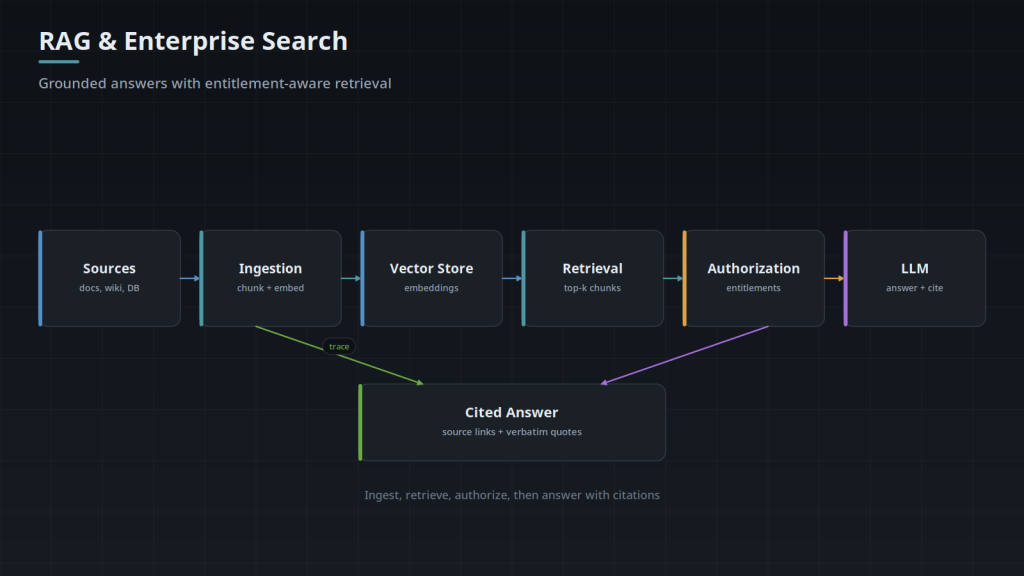
RAG and enterprise search is how you get an AI that answers from your documents — accurately, with citations, and only for the people allowed to see them. Software Depo builds retrieval-augmented generation over your real content: policies, contracts, manuals, tickets, and knowledge bases, wherever they live.
Retrieval Is Where RAG Succeeds or Fails
A RAG system is only as good as what it retrieves. Get chunking, indexing, and ranking wrong and the model answers from the wrong passage — confidently. We engineer the retrieval layer as carefully as the generation: how documents are split, how they are indexed, how hybrid and semantic search are combined, and how freshness is maintained as content changes.
What We Build
- Document ingestion from SharePoint, Google Drive, databases, and file stores
- Permission-aware retrieval — users only get answers from content they are allowed to see
- Chunking and indexing tuned to your document types
- Hybrid and semantic search for recall and precision
- Citations, so every answer can be verified against its source
- Freshness handling so updated documents are reflected, not cached stale
- Evaluation, including access-control leakage testing
RAG or Fine-Tuning?
For most business knowledge, RAG beats fine-tuning: it is cheaper, it stays current as documents change, and it can cite its sources. Fine-tuning has its place — for style, format, or narrow tasks — and we will tell you the rare cases where it earns its cost. Usually the answer is retrieval done well.
Security Is Not Optional
A retrieval system that ignores permissions is a data-leak waiting to happen. We enforce access controls at retrieval time and test specifically for leakage — can user A get an answer sourced from a document only user B should see? That test is part of every RAG delivery.
Tell us what knowledge should be searchable — the sources, who may see what, and the questions people need answered. We will scope a RAG system grounded in your content.
Related services
- Enterprise Search and Website Answer Agents — Search and answer agents for your site and intranet: enterprise search and answer agents.
- Document Intelligence and Language Automation — When the documents themselves are the work: document intelligence.
What Is RAG?
Retrieval-augmented generation means retrieving relevant material from your own content and giving it to the model as context, so the answer is grounded in your documents rather than in the model’s training data. It is how an assistant answers questions about your policies, your contracts and your products, with citations.
The retrieval half is where the quality lives. Most disappointing RAG deployments are not model problems — they are retrieval problems. If the right passage is not retrieved, no model can produce the right answer.
RAG or Fine-Tuning?
They solve different problems and are frequently confused. RAG supplies knowledge: facts that change, that must be cited, or that are specific to your organization. Fine-tuning shapes behaviour: tone, format, adherence to a particular style of response.
If the requirement is “answer questions about our documents”, that is RAG. Fine-tuning a model on a document set to teach it facts is an expensive way to get an unciteable, stale answer that cannot be updated when the document changes.
Why Do RAG Systems Give Poor Answers?
- Bad chunking. Splitting documents at arbitrary lengths severs tables, clauses and context. Chunking should follow document structure.
- Retrieval that misses. Pure vector similarity struggles with exact terms — part numbers, clause references, product codes. Hybrid keyword-plus-vector retrieval usually beats either alone.
- Stale or duplicated sources. Three versions of a policy in the index means the model may cite the wrong one. Source hygiene is most of the work.
- No permission filtering. Retrieval must respect who is asking. An index that ignores permissions will answer questions the asker was never entitled to ask.
- No evaluation. Without a test set of real questions and known-good answers, quality is a matter of opinion and regressions go unnoticed.
What Does a RAG Project Involve?
Establishing which sources are authoritative and who owns them; building ingestion that respects document structure and keeps the index current as content changes; implementing retrieval with permission filtering; designing answers that cite their sources so users can verify; and building an evaluation set before launch rather than after complaints.
The unglamorous part — deciding which of the four copies of a policy is the real one — is usually the part that determines whether people trust the system.
Related: enterprise search and answer agents · document intelligence · evaluations.
What Ingestion Actually Involves, Source by Source
Ingestion is not one connector, it is a separate piece of engineering per source, because each system has a different idea of what a document is. A SharePoint document library returns files with version history and per-item permissions. Google Drive returns files that may sit in a shared drive with its own membership or in one person's My Drive. A ticket system returns a thread of comments where the useful content is a fragment of the record. A database returns rows that have to be assembled into something worth retrieving at all. The connector decides what a chunk will eventually represent, so getting that unit wrong at ingestion is expensive to correct later.
Every source exposes a different change feed, and its shape decides how the index stays current. Rate limits shape the design as much as the API surface does: Microsoft Graph throttles with HTTP 429 and a Retry-After header and expects the client to back off, so a first full crawl of a large tenant is throttled work that runs for hours or days no matter how the pipeline is written.
- Microsoft Graph exposes delta queries on drives and lists. You hold a delta token, ask for what has changed since it was issued, and get a new token back for next time. If the token is too old or the service resets it, the call fails and the only recovery is a full re-enumeration of that scope.
- Google Drive's changes API works from a start page token, and the token is scoped: a shared drive has its own change feed, separate from a user's own corpus.
- Push notifications from either platform are subscriptions with a maximum lifetime, so a renewal job has to run or the feed goes quiet without ever raising an error. Delivery is not guaranteed either, which makes a notification a signal to go and look rather than a record you can rely on by itself.
- SMB and NFS shares expose a modified timestamp and little else. There is no feed to subscribe to.
- Databases and ticket systems usually need an updated_at column or an API filter on modification time, plus a decision about whether a change to one field is worth re-embedding the whole record.
Early Binding, Late Binding, and Where the Permission Filter Runs
There are two ways to make retrieval respect permissions, and the choice constrains everything downstream. Early binding copies the access control list onto each chunk at ingestion time, so the index carries a set of principals per chunk and the query filters against it. Late binding stores no permission data and asks the source system, at query time, whether this user may see this document. Early binding is fast and keeps working when the source is unavailable, but it is only as current as the last ingestion run. Late binding is always correct and costs a round trip per candidate document, which stops being workable once the candidate set is more than a handful.
The practical middle is to index group identifiers rather than resolved user lists, and to resolve the asker's transitive group membership at query time from the identity provider. Someone who leaves a group loses access at their next query, with nothing reindexed. Nested groups have to be expanded transitively rather than one level deep, and explicit deny rules do not fit the model at all: a deny is an exclusion rather than a member of the allowed set, so it has to be carried and applied as a separate list.
Whichever binding is used, the filter has to run inside the search rather than after it. Retrieving the top ten chunks and then discarding the ones the user may not see returns three results, while the seven they were entitled to sit further down the ranking, never retrieved. Vector indexes differ in how well they support this: filtered search over an HNSW graph can degrade sharply when the filter is highly selective, because traversal keeps landing on neighbors that fail the filter, and some engines respond by falling back to a brute force scan of the filtered subset.
Chunking Is Limited by the Format and by the Embedding Model
Chunking that follows document structure requires the structure to exist in the file, and often it does not. A PDF produced by a scanner is an image and needs OCR before anything else can happen. A PDF produced by a layout tool is a set of positioned glyphs with no headings, no paragraphs and no reliable reading order, and a two column page extracted naively interleaves the columns line by line. DOCX and HTML carry real heading hierarchies that can be used directly. Extraction is therefore the step that decides whether structural chunking is possible at all.
The embedding model imposes a second constraint that is easy to miss. Every embedding model has a maximum sequence length, and a chunk longer than that is truncated rather than rejected: many widely deployed models cut input at 512 tokens and do it silently, with no error anywhere to tell you that the second half of the chunk was never embedded. The generation stage has its own separate budget, because retrieved chunks, system prompt and conversation history all compete for one context window, so a larger chunk size means fewer chunks fit.
The embedding model is also a long term commitment. Vectors produced by two different models are not comparable, so switching models, or upgrading to a new version of the same one, invalidates every vector in the store and requires re-embedding the entire corpus. That is a scheduled reindex whose cost scales with corpus size, and a reason to keep raw chunk text and its metadata in a store you control rather than only inside the vector index.
- A table split across chunks needs its header row repeated into each piece, otherwise the second half is a grid of numbers with no labels attached to them.
- Clause and section numbering makes a good chunk boundary in contracts and policies, because the clause reference is both what people search for and what a citation has to resolve to in the original.
- Spreadsheets are not documents. A sheet is usually better handled as structured data than as text, and flattening it into prose for embedding discards the relationships that made it useful.
- Long documents need either chunk overlap or a parent document reference, so a passage that answers the question but depends on a definition three pages earlier still carries enough context to be read correctly.
Fusion, Reranking, and Telling Retrieval Failures from Generation Failures
Hybrid retrieval means running two searches and combining them, and the combination is the part that needs care. A BM25 score and a cosine similarity are on incompatible scales and cannot simply be added. The usual answer is to fuse by rank rather than by score: reciprocal rank fusion gives each result a weight of 1/(k + rank) in each list, with k a smoothing constant commonly set to 60, and sums the weights across lists. It needs no per-corpus tuning, which makes it a reasonable default before anything more elaborate is attempted.
Reranking is a second pass over the fused candidates. A cross encoder takes the query and one passage together and scores their relevance directly, instead of comparing two vectors that were computed independently and never saw each other, which is why it is more accurate and also why it cannot be precomputed. The usual pattern is to retrieve fifty to a hundred candidates cheaply and rerank them down to the five or ten that go into the prompt. It is also the main latency line item.
- Measure the retriever separately from the answer. Recall at k, the fraction of test questions where a passage containing the answer appears in the top k results, is a property of retrieval alone and does not depend on the model that writes the answer.
- When an answer is wrong, paste the correct passage into the context by hand and ask again. If the answer is now right, the failure was in retrieval. If it is still wrong, the failure is in the prompt or the generation step, and no amount of chunking work will fix it.
- If recall at fifty is high but recall at five is low, retrieval is finding the passage and ranking is burying it. That is a fusion and reranking problem, not an indexing problem.
- If recall at fifty is also low, the passage is not being found at all, which points at extraction, chunking or the query itself rather than at ranking.
When a Retrieval Pipeline Is Not the Answer
Some questions that look like retrieval problems are not, and an ingestion pipeline is a standing cost that has to be maintained for as long as the content it indexes exists. Each of the cases below has a cheaper answer that does not require an index to keep in sync.
- A small and stable corpus can go straight into the prompt. If the whole handbook is forty pages, there is no retrieval problem to solve, and prompt caching makes repeating that context across requests inexpensive.
- Text-to-SQL and RAG are different systems, and answering arithmetic questions by retrieving row text produces confident wrong numbers.
- If the content lives in one system that already has a working search, configuring that search is cheaper than copying the corpus elsewhere and then having to keep both the copy and its permissions correct.
- If the answers are not written down anywhere, retrieval has nothing to retrieve. A system built over a corpus that does not contain the answer will still produce a fluent response assembled from adjacent material, which is worse than no answer.
- Where an answer has to be exact and identical every time, a lookup table or a decision tree fits better than a generated response, because it can be verified once instead of evaluated statistically.
Frequently Asked Questions
Is a vector database the same thing as RAG?
No. RAG is a pattern: retrieve passages from your own content, put them in the model's context, and generate an answer that cites them. A vector database is one possible implementation of the retrieval step, and it is not a required one; retrieval can be BM25 in Elasticsearch or OpenSearch, or Postgres full-text search, with no vector store at all. Where vectors are wanted, pgvector inside an existing Postgres instance often does the job, and it keeps chunk text, metadata and permission attributes in one store instead of two systems that have to be kept in sync.
What has to be in place before a RAG project can start?
Access, questions, and content that actually exists in writing. Access means a service account or app registration in each source system that can read both the content and the permission model, because retrieval has to reproduce who may see what and not only what the text says. Questions means a set of real ones, collected from the people who will use the system rather than invented by the project team. And sources with no API, such as a scanned archive or a vendor portal with no export, have to be exported by other means or ruled out of scope before any estimate means anything.
How does connecting to SharePoint or Google Drive actually proceed?
It starts with an application identity and administrator consent, not with code. In Microsoft 365, an app registration requesting application-level Graph scopes such as Files.Read.All or Sites.Read.All needs a tenant administrator to consent, and those scopes are tenant-wide; SharePoint's Sites.Selected model instead narrows an app to specific sites granted one at a time, which is usually what you want for a first deployment. From there the sequence is a full enumeration of one site or drive to build a baseline index, capture of the change cursor at the end of that run, then incremental updates driven from the cursor. Google Workspace follows the same shape with a service account and, where user impersonation is required, domain-wide delegation authorized in the admin console.
How does the index handle documents that are deleted or moved?
Through the change feed where one exists, and through a reconciliation pass where one does not. Change feeds report deletions explicitly, so a document removed at the source can be removed from the index on the next incremental run. A crawler that only looks for a modified date later than its last run has no way to see something that is no longer there, so those sources need a periodic pass that compares the set of identifiers in the index against the set in the source and removes what is missing. The same pass catches documents that moved into a differently permissioned location without their content changing, which is the case most likely to leak.
Can ticket systems and databases be used as sources?
Yes, but tickets have to be treated as records with a lifecycle rather than as bodies of text. The useful content in a ticket is usually the resolution, not the reporter's original description of the symptom, and indexing the whole thread undifferentiated means the model retrieves the wrong half of the conversation. Tickets also carry customer personal data, including names, email addresses and sometimes account identifiers, which has to be redacted or scoped before it enters an index a wider audience can query. Where a system has both a document side and a structured side, that is two retrieval paths, built and tested separately.
What does the customer have to decide, rather than us?
The permission semantics for the awkward cases. What happens when a document is shared by link to anyone holding the URL; whether a manager inherits access to a direct report's private folder; whether contractors in a guest tenant are treated as employees for retrieval purposes; how an item with broken permission inheritance is handled relative to the library it sits in. Those are policy decisions rather than engineering ones, and the retrieval filter has to encode one specific answer for each of them. Deciding them late means changing the filter and rerunning every access test that depends on it.