
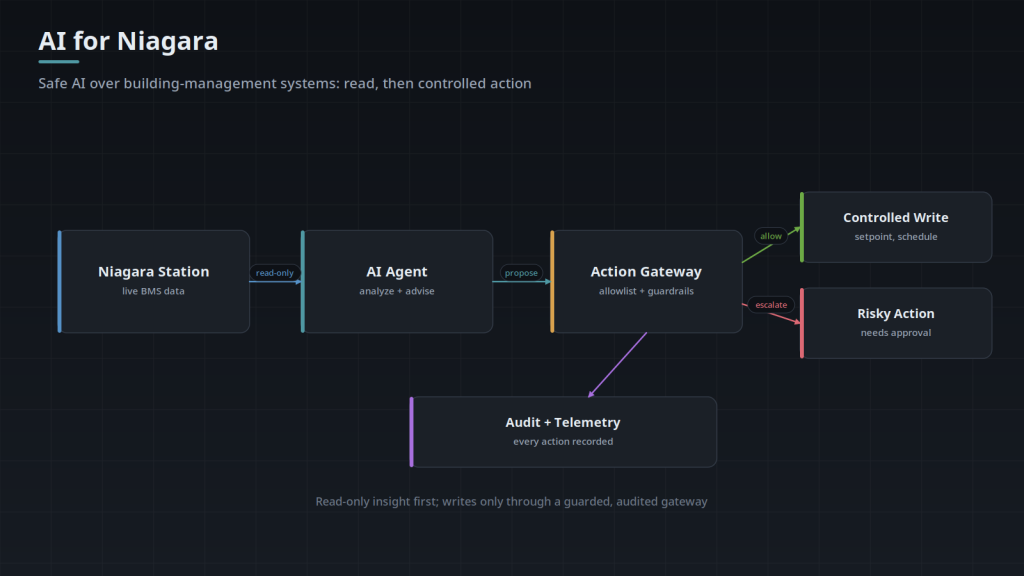
AI development for Niagara Tridium and building automation is Software Depo’s most defensible specialty: we combine production AI-agent engineering with real operational-technology experience. The result is AI added around controlled Niagara workflows — reading data, drafting reports, triaging alarms, answering engineering questions — never given unrestricted control over a building.
The AI is ours. The Niagara engineering is delivered by our sister practice SoftwarePile, the SoftwareMile Niagara Framework development team — so every integration is grounded in genuine station and module expertise, not AI guessing at building systems.
Safety First, Always Read-Only to Start
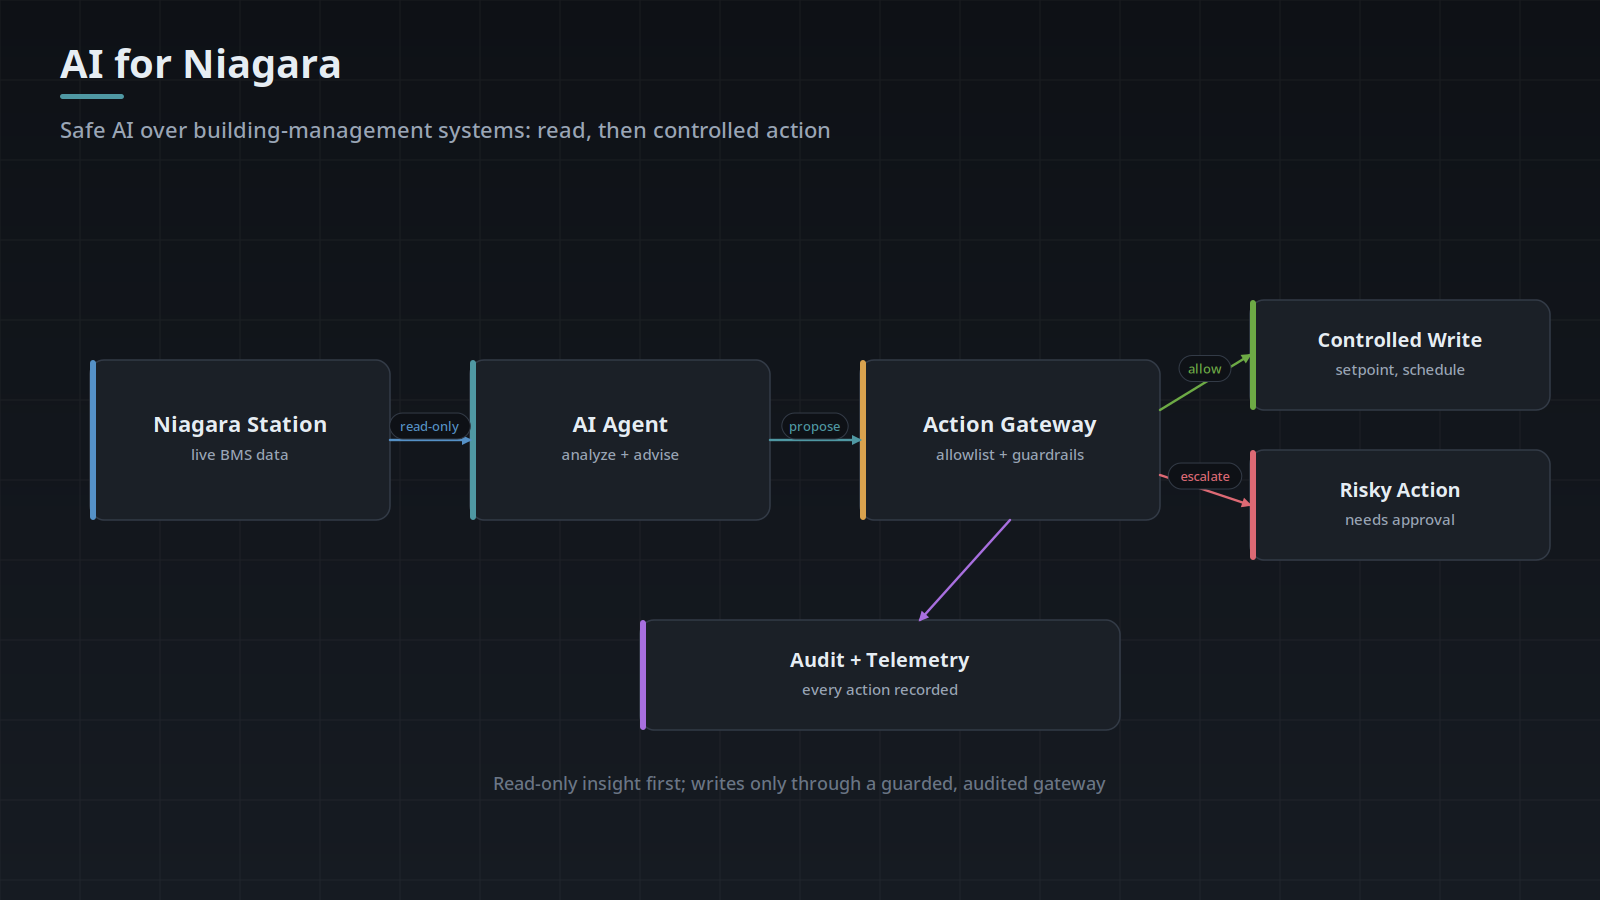
Buildings are operational systems where a wrong command has physical consequences. Every AI-for-Niagara engagement starts read-only: the agent can query, summarize, and recommend, but any consequential action requires scoped permissions, validation, audit logging, and human approval. We add write capabilities only deliberately, one approved action at a time.
Niagara Knowledge Agent
Answers from your engineering standards, sequences of operation, customer SOPs, Niagara manuals, module documentation, commissioning records, service tickets, and site-specific notes — with citations, and respecting who is allowed to see what. It turns a filing cabinet of tribal knowledge into something a technician can query in plain language.
Niagara Alarm Triage Agent
Receives or queries an alarm, gathers related points, histories, and equipment context, compares the condition against SOPs and known faults, prepares a probable-cause summary, recommends checks, and drafts or enriches a service ticket — then requires human confirmation before any consequential action. It shortens the path from alarm to informed response.
Niagara Station Audit Agent
Automated checks across a station or fleet: missing histories, incomplete alarm routing, naming-standard violations, untagged equipment, disabled or stale points, license headroom, down devices, communication faults, and configuration inconsistencies — producing a prioritized, technician-ready report.
Niagara Engineering Copilot
Assists developers and engineers with BQL creation, Baja API examples, module documentation, code analysis, station-report interpretation, migration checklists, test-case generation, and error-log explanation — accelerating engineering work without replacing engineering review.
Niagara MCP Server
A secure MCP server that exposes only approved capabilities to AI — read station metadata, query histories, retrieve alarms, run approved reports, read module inventories, search documentation, create a draft ticket. It starts read-only; write actions are added only through scoped permissions, validation, audit logs, and approval steps. For independent security review of that boundary, our sister practice BulletproofSoft assesses AI and MCP deployments.
Niagara Workbench MCP — In Development
We are currently building a deeper MCP layer that gives a desktop AI assistant governed control of the Niagara Workbench itself — creating and editing wiresheets, managing running stations, and carrying out engineering tasks that today require someone driving the tool by hand. It runs through the same gates as everything else on this page: individually scoped tools, allowlisted actions, audit logging, and human approval for anything consequential.
Status: in development. We are describing this as a reference architecture and an active build, not something you can buy today. It is genuinely more capable than the Niagara MCP work we have published publicly — and we would rather tell you it is unfinished than imply otherwise. When it is production-ready, this page will say so plainly.
AI Autopilot with Human Escalation
Autopilot does not mean unattended control. It means the agent operates autonomously within a defined scope — the routine, allowlisted, low-consequence decisions — and hands anything beyond that scope to a person rather than guessing. When a decision exceeds what it is permitted to make alone, it escalates: a WhatsApp, SMS, or phone message to the responsible manager, carrying the context needed to decide quickly.
That escalation path is the feature, not a fallback. An agent that knows the boundary of its own authority — and reaches a human when it hits that boundary — is the difference between automation you can leave running and automation you have to supervise. Every decision, escalation, and action lands in the audit trail either way.
We have delivered an AI autopilot for a Niagara station at a major North Carolina electric utility, built to this pattern.
Station Status Widgets and Dashboards
Alongside the agent work we build Niagara station status widgets and dashboards — surfacing live station health, device and communication state, and the conditions worth acting on, in a form operators and technicians can read at a glance. These are delivered, working components; they are also what makes the AI layer above them useful, because an agent reasoning over a station is only as good as the visibility into it.
Automated Reporting
Daily alarm summaries, fleet-health reports, station-compliance reports, energy anomalies, software and module inventories, executive summaries, and technician-ready diagnostic packages — generated on schedule from live station data.
The Niagara Foundation This Runs On
None of these agents work on messy data. AI on a building whose points are unmapped, mislabeled, or inconsistently named produces confident nonsense — so the AI layer is only ever as good as the integration beneath it. That foundation is SoftwarePile’s Niagara engineering, and their team writes about exactly the groundwork this depends on:
- AI for Building Automation: What’s Real and What’s Hype — the same read-only, human-in-control philosophy, from the building-systems side
- Project Haystack and Semantic Tagging — why building data needs structure before any analytics or AI can use it
- BACnet vs Modbus — the protocol integration that gets clean data into the system in the first place
Tell us about your Niagara environment and what you want AI to help with — your Niagara version, station count, and whether you need read-only insight or approved actions. We scope from a safe starting point.
Related services
- Private and On-Premise AI Deployment — Building-systems data usually stays on-premise: private and on-premise AI.
What the MCP Boundary Is Actually Made Of
MCP is a JSON-RPC 2.0 protocol. The client and server negotiate capabilities during the initialize exchange, and the server then advertises three separate primitives: tools, which the model can decide to call on its own; resources, which the client reads on request; and prompts, which a person selects deliberately. Which primitive a capability lands in is a design decision with consequences. Exposing a station inventory as a resource the client fetches when asked is a narrower exposure than exposing it as a tool the model invokes whenever it judges the inventory relevant.
Tool annotations such as readOnlyHint and destructiveHint travel with the tool definition, but they are advisory metadata for the client to display and reason about. Nothing in the protocol prevents a server whose tool is labeled read-only from writing. Enforcement has to sit below the protocol, in the code path of the tool and in the credentials the server actually holds. A server process that only ever possesses read credentials cannot be talked into a write, whatever the model decides to call and whatever a compromised client sends.
Transport choice moves the boundary. Running the server over stdio as a subprocess of a desktop assistant puts the trust boundary at the workstation and the person logged into it. Running it over streamable HTTP so several clients share one server means the server now needs authentication, per-caller identity, and origin validation, because tool calls arrive over a network the operator does not control. The MCP guidance to validate the Origin header and bind local servers to the loopback interface exists because a browser page can otherwise reach a server listening on localhost.
- Prefer narrow input schemas to general ones. A tool that takes a station identifier and a point path constrains what can be asked of it. A tool that accepts a free-form query string inherits every capability of the query language behind it, including the parts nobody meant to expose.
- One capability per tool, named for exactly what it does. The model selects tools from names and descriptions, so two similarly described tools get confused with each other, and the fix is naming, not a larger model.
- Validate arguments server-side against an allowlist, not with schema validation alone. JSON Schema confirms that a station identifier is a string; it does not confirm that this caller is allowed to read that station.
- Cap and paginate results inside the tool, and return the cap in the response. A query matching ten thousand rows should return a bounded page plus a total, so the model can say the list was truncated instead of treating one page as the whole.
- Return failures as structured tool errors rather than letting exceptions surface as raw text. A model that receives a typed error can correct the call; a model that receives a stack trace tends to report it as a finding about the building.
Grounding, Citations, and Permission-Aware Retrieval
Retrieval quality is set by chunking and metadata, not by the model. A sequence of operations split across a chunk boundary loses the setpoint row that gave the paragraph its meaning, and a chunk stored without its document title, revision, and site cannot be cited in a way a technician can verify. A citation that names only a filename is close to useless when the file is a 200 page manual; the citation has to resolve to the passage that was actually retrieved, and to the revision it came from.
Permission filtering belongs in the retrieval query, not in a pass over the results afterward. Once a passage is in the context window the model can restate its content without reproducing the citation, so removing a citation does not remove the information. The retrieval identity should be the identity of the person asking, resolved against your existing directory or SSO groups, rather than a service account holding the union of everyone's access with filtering applied later.
An index built once drifts away from the documents it represents. A revised SOP leaves its previous embedding in the index unless the document is re-indexed on change, and the agent will keep citing a superseded procedure with complete confidence, because from its side nothing looks wrong. Withdrawn documents matter as much as edited ones: stale vectors outlive the files they came from. Where two sources genuinely disagree, such as a general manual and a site-specific note, precedence has to be stated explicitly in metadata, or the answer blends them into something that matches neither.
- Store document title, revision, effective date, site, and access group as chunk metadata. That metadata is what makes both the permission filter and a verifiable citation possible.
- Re-index on document change and delete chunks for withdrawn documents on the same code path, so removal is not a separate process someone has to remember to run.
- Resolve the asking user's groups at query time and filter inside the vector or keyword search, not after the passages have been retrieved.
- Keep a fixed evaluation set of questions with known answers and known source documents, and re-run it after every index rebuild, prompt change, or model change. Without it, a regression is invisible until a technician acts on a wrong answer.
- Score "that is not in the documents I can see" as a correct answer when it is correct. An agent that never abstains is not more useful, it is less honest.
- Prefer an extractive quote with a link to the passage over a paraphrase for anything a technician is expected to act on.
Context Limits and Why the Tool Set Decides Answer Quality
No station of any real size fits in a context window, and the ones that would fit should not be loaded that way. Filling context degrades retrieval within it, because relevant details compete for attention with thousands of irrelevant ones, and the whole payload is re-sent on every turn, so latency and cost scale with the padding rather than with the question. The working design is a small set of tools that each return a narrow slice on demand. The practical consequence is that the ceiling on answer quality is the tool set, not the model.
The characteristic failure mode is a question no tool can answer. The model does not stop; it reshapes the question until an available tool fits, then answers from whatever adjacent data it could reach, fluently. The diagnostic is the tool-call trace, and it separates two problems that look identical from the outside. If the trace shows the model bending the question to fit an existing tool, that is a missing tool, and no prompt change will fix it. If the trace shows the right tool returning the right data and the summary still misstating it, that is a prompt or model problem, and adding tools will not help.
Long sessions decay in a way that is easy to miss. As a conversation grows, earlier turns get summarized or dropped, and a constraint stated once at the beginning stops being present in the context that produces turn forty. Scope constraints that matter, such as which site is in play and what the agent is permitted to do, belong in the system instructions and repeated in tool results, not in conversation history.
- Return counts and aggregates by default, with a separate drill-down tool for detail, rather than returning rows because rows happened to be available.
- Include units, timestamps with explicit offsets, and quality or reliability flags in every result. A number without units is where a wrong conclusion starts, and a stale value that looks current is worse than a gap.
- Distinguish an empty result from a failed one in the response body. "No alarms matched" and "the query did not run" have to look different to the model, or an outage reads as good news.
- Log every tool call with its arguments, result size, and duration. That trace is the first artifact to read when an answer looks wrong, and the only one that separates a missing tool from a bad summary.
Escalation Paths, Approval Binding, and Replay Safety
A message delivered is not a decision made. Delivery receipts on SMS and WhatsApp confirm that a handset accepted the message, not that a person read it, understood it, or is awake. An escalation therefore needs an explicit acknowledgment step and a timeout that moves to the next name on the roster, otherwise an escalation sent to somebody mid-flight becomes, silently, no escalation at all.
Messaging channels also impose constraints that shape the design. The WhatsApp Business Platform only lets a business open a conversation outside the 24 hour customer service window using a message template approved in advance, so escalation text is a registered template with variables rather than free prose composed at the moment. Inbound SMS proves control of a handset, not the identity of a person, and sender information on these channels is not a credential. The practical pattern is that the notification carries the context and a link, while the approval itself happens in an authenticated view where the approver is actually identified.
Approval only means something if it is bound to the exact action proposed. An approval token should reference the specific call and its arguments, be single use, and expire, so that consent given for one action cannot be replayed against a different one that arrives later. Any call that changes state should carry an idempotency key, so a network retry is deduplicated at the server instead of repeated at the equipment. Without both, a slow connection and a resent request are indistinguishable from a deliberate second command.
- Give every escalation a correlation ID that ties the trigger, the evidence retrieved, the proposed action, the approver, the decision, and the result into one record that can be replayed later.
- Bind the approval to a hash of the proposed call and its arguments, and void it if either changes between proposal and execution.
- Define an acknowledgment timeout, a next in line, and quiet-hours rules that state what is worth waking someone for and what waits until morning.
- Make refusal first class. Recording "no" has to be as easy and as auditable as recording "yes", or people approve things to clear the notification.
- Deduplicate and rate-limit before escalating. One root cause can generate a burst of alarms, and an agent that pages a person for each of them teaches that person to ignore it.
When an Agent Is the Wrong Tool
If a question has one correct answer computable from a query, write the query. A threshold, a scheduled report, or a rule is deterministic, testable, cheap to run, and produces the same output for the same input every time, which is what you want for anything that has to be defended afterward. Language model output varies between runs on identical input. That variance is acceptable in a summary a person reads and unacceptable in a decision that has to be reproducible.
Volume decides whether the agent work pays for itself. Building and maintaining a triage loop is justified where alarm and ticket volume exceeds what people can actually read; a site producing a handful of alarms a week does not need one, and a person will beat it on both speed and accuracy. The same test applies to a knowledge agent: it needs a corpus that contains the answers. If your standards and sequences live in three people's heads, the work to do first is writing them down, and that work has value whether or not an agent ever reads the result.
Agents earn their place where the input is unstructured, where the path branches on judgment, and where an answer requires joining sources that were never designed to be joined. A ticket written in prose, a manual, a commissioning note, and a point history are four different shapes of information, and reconciling them is the part that resists being written as a rule. That is a different problem from evaluating a threshold, and it is worth being clear about which one you have before anyone builds anything.
- Use a rule or a threshold when the condition can be expressed over known points, and keep it as a rule even after an agent exists.
- Use a scheduled report when what you want is the same view on the same cadence with no interpretation step.
- Use search when what you want is to find the document, not to have an answer synthesized from several documents.
- Use an agent when the useful output is a judgment across unstructured sources, and when a person will still review it before anything happens.
Frequently Asked Questions
Is this a product we install, or custom development?
It is engineering work built against your environment, not a package with an installer. The agents, the retrieval layer, and the MCP server are configured around your specific station structure, naming, document set, and permission model, because those are exactly the things that determine whether the output is right. Station status widgets, dashboards, and scheduled reports are delivered, working components that can go in earlier. The Workbench MCP layer described above is in development and is not something you can purchase today.
What has to already exist before an AI layer is worth adding?
Three things: an integration whose points are mapped and named consistently, histories that are actually collecting for the points you care about, and documents that exist as files rather than as institutional memory. You also need a source of identity, typically your existing directory or SSO, because permission-aware answers require knowing who is asking. The integration groundwork itself is Niagara engineering, delivered by SoftwarePile rather than by the AI side of the work.
Where does the MCP server run, and does our data leave the site?
The server runs beside the systems it reads, which for building systems usually means on-premise or in your own tenant, and it can be configured for outbound-only connectivity so nothing new listens for inbound connections. What leaves that boundary depends on the model deployment you choose: a hosted model receives the text of the questions and the retrieved passages sent to it, while a self-hosted model keeps that traffic inside your network at the cost of capability and hardware. The retrieval index, the audit log, and the tool call traces live wherever you require them to, and that is a decision worth making before the build rather than after.
Which models does this depend on, and are we locked to one?
MCP is model-agnostic by design: the server exposes tools, resources, and prompts, and any compliant client can use them, so the model is a component rather than the architecture. In practice models differ in how reliably they select the right tool and how readily they abstain when a question is not answerable from what they retrieved, so changing the model is a change worth re-running the evaluation set against. The tool definitions, permission model, audit trail, and retrieval index do not change when the model does.
How does the integration actually proceed?
It starts with a read-only inventory: what the station exposes, which points are historized, what documents exist, and who is allowed to see what. From there the tool set is defined and built narrow, retrieval is wired with permission filtering inside the query, and the whole thing is measured against a fixed set of questions with known answers before anyone relies on it. Only after that does the agent move from answering to proposing, and only after proposals have been reviewed in practice does any scoped write capability get added, one approved action at a time.
What do we have to provide or decide?
Read-only credentials scoped to the systems in play, network access to reach them, and a document set with an owner who can say which revision is current. You also decide the permission mapping, meaning which groups can see which documents and which stations, and the escalation roster with its quiet-hours rules. The decision that matters most is the list of actions that may ever be taken automatically, because most of the rest of the design follows from where that line sits.
Can the agent be wrong, and what happens when it is?
Yes. Language models produce fluent output regardless of whether the retrieval behind it was adequate, so the failure looks like a confident answer rather than an error. That is why consequential actions are proposals for a person to approve rather than actions taken, why answers carry citations that can be checked against the source passage, and why every tool call is logged. When an answer is wrong, the tool-call trace tells you whether the cause was a missing tool, a stale document, a permission filter that hid the right source, or the model itself, and those have four different fixes.