Software Depo builds AI agents that do real work inside real businesses: they answer from your documents, act through your tools and APIs, and route sensitive steps through human approval. We are the SoftwareMile specialist practice for AI-agent development and intelligent automation.
What We Build
Knowledge and document agents that answer accurately from your policies, contracts, manuals, and tickets — with citations. Customer-service and employee-support agents that resolve routine requests and escalate cleanly. Workflow agents that move work between your systems: intake, triage, drafting, scheduling, reporting. Engineering, coding, and QA agents that work inside your repositories with scoped permissions. Multi-agent systems where specialized agents coordinate under an orchestrator with clear boundaries.
Built for Production, Not Demos
Every agent ships with scoped permissions, audit trails, evaluation suites run before rollout, monitoring in operation, and human-approval gates where actions have consequences. Private and hybrid deployments are supported when data cannot leave your environment.
Platforms We Implement
Custom agents on leading models; MCP servers and connectors so agents reach your systems safely; Microsoft Copilot Studio and Microsoft 365 Copilot; Claude and Claude Code setup including Skills, hooks, and MCP integrations; Codex setup including repository agents and Skills; retrieval-augmented generation and enterprise search.
How an Engagement Runs
Discovery maps the use case, data sources, tools, and approval requirements. We prototype against your real documents and systems, evaluate against agreed test sets, then deploy with monitoring and a support arrangement. You see behavior evidence before anything goes live.
Tell us about your agent use case — include the data sources and tools involved, your existing AI platform if any, and whether deployment must stay private. We will scope it from the first conversation.
Related services
- AI Agent Integration Services — Connecting agents to the systems you already run: AI agent integration.
- Agentic AI Consulting and Implementation — Not sure where agents fit yet? Agentic AI consulting.
What Is an AI Agent?
An AI agent is a system that uses a language model to decide and act, not merely to answer. Given a goal, it can choose which tools to invoke, read the results, and take further steps — looking a record up, updating a system, escalating to a person — rather than returning text and stopping.
The distinction from a chatbot is action and consequence. A chatbot that is wrong wastes someone’s time. An agent that is wrong creates a record somebody has to find and undo. That difference is what drives everything about how agents should be built.
What Makes an Agent Reliable Enough for Production?
- Bounded scope. Agents that do one job well are far more reliable than agents that do everything adequately.
- Scoped permissions. Acting as the requesting user rather than through a shared account with broad access.
- Human approval where it matters. On spending, customer contact, and deletion, until the logs justify removing the step.
- Evaluation before rollout. A test set of realistic tasks with known-good outcomes, run before deployment and again after every prompt or model change.
- Honest failure. An agent that says it cannot reach a system beats one that answers from stale context.
- Complete audit trail. What it did, why, on whose behalf.
Where Do Agents Actually Pay Off?
The strongest cases share a shape: a task done often, by several people, that requires pulling information from more than one system and applying rules that are written down somewhere. Support triage, quote preparation, document review, internal question answering over policies and procedures, and status reporting across tools all fit.
Weak cases also share a shape: work that is genuinely different every time, work where the judgement is the value, and work done rarely. Automating those costs more than it returns.
How Should a First Agent Project Be Scoped?
Pick one workflow with a named owner, a measurable cost in staff time, and a bounded blast radius. Ship it read-only first and watch what people actually ask for — it is reliably different from what was specified. Then add the single write action that saves the most effort, with approval on it.
This sequence produces a working system in weeks and real evidence about whether the wider programme is worth funding. Broad multi-department agent rollouts commissioned before anything has run in production are where budgets go to die.
Related: agentic AI consulting · agent integration · evaluations and guardrails.
What Breaks Between the Demo and the Hundredth Run
A demo passes because one person drove it once, with a clean input, while watching. Production differs in three ways that all compound: inputs arrive incomplete or malformed, tools fail intermittently for reasons unrelated to the agent, and the same task runs many times, so behavior that is rare becomes routine. An agent that is right 95 percent of the time on a task run twice a day is wrong about three times a month. At the same rate on a task run 500 times a day it is wrong 25 times a day, and each of those may have written something.
Most production failures are not the model stating something false. They happen at the loop and at the tool boundary: the agent calls a tool, the call fails in a way the wrapper did not distinguish from success, and everything after that step is reasoning over a bad premise. These are engineering defects with engineering fixes, which is why they are worth naming separately from accuracy.
The failure modes below are the ones to design against before the first write action ships. Each has a distinct fix, and none of them is fixed by rewriting the prompt.
- Non-idempotent retries. A create call that times out after the server already committed looks identical to one that never arrived. Client-generated idempotency keys, or a read-before-write check against a natural key, are what make a retry safe to attempt at all.
- Error text absorbed as data. A 403 body, a rate-limit notice, or an HTML error page returned as a tool result becomes context the model reasons over and often paraphrases as fact. Tool wrappers should raise on any non-2xx response rather than hand the body back as content.
- Context growth across steps. Every tool result stays in the transcript, so a long run pushes the original instruction far behind the most recent output. A cap on step count, plus a policy for summarizing or dropping older results, is the control that actually holds.
- Partial success in multi-step writes. Step three failing after steps one and two committed leaves an inconsistent record that nobody is looking for. Either every write in the sequence has a compensating action, or the writes are collapsed into one call the target system commits atomically.
- Tool selection ambiguity. Two tools whose descriptions overlap produce different choices on different runs from the same input. That is a schema problem, fixed by narrowing descriptions and merging near-duplicate tools, not by instructing the model which one to prefer.
What Has to Exist on Your Side Before an Agent Can Act
The identity model is where integration work actually lands. Per-user access means an OAuth 2.0 authorization code flow with a registered application, a consent grant, and refresh tokens held somewhere encrypted at rest, with a plan for what happens when a grant is revoked. A service identity is faster to stand up and sees whatever that account can see, which is why it needs a purpose-built account with a narrow role rather than an existing administrative one.
Permission changes usually take effect at token refresh rather than immediately. Access tokens are commonly valid for around an hour, so access removed in the source system can remain usable until the current token expires. Where that window matters, the tool layer re-checks authorization on each call instead of treating a valid token as proof of current entitlement.
Where a system has no MCP server, the choice is between adopting a vendor or community server and writing a thin one over the system's API. A published server saves the schema work and brings its own release cadence and its own opinion about what the tools should be; one you write matches your workflow and is yours to maintain as the API changes. Neither option removes any of the identity work above. Beyond identity, the list a scoping conversation works through is short, and every item on it is something only you can provide.
- An API, an existing MCP server, or something equivalent for each system in scope. UI automation against systems with no API is possible and breaks on layout changes.
- A named owner for each system who can approve the application registration and the scopes it requests. This is usually the slowest item in the whole project.
- A non-production tenant or sandbox holding representative data, because write actions cannot be exercised anywhere else without consequences.
- A destination for logs of prompts, tool calls, and results, with a retention period decided by whoever owns that data rather than by the project.
- A decision on where inference runs, because that determines what leaves your network and constrains which models are available to you.
Where MCP Servers Sit in the Architecture
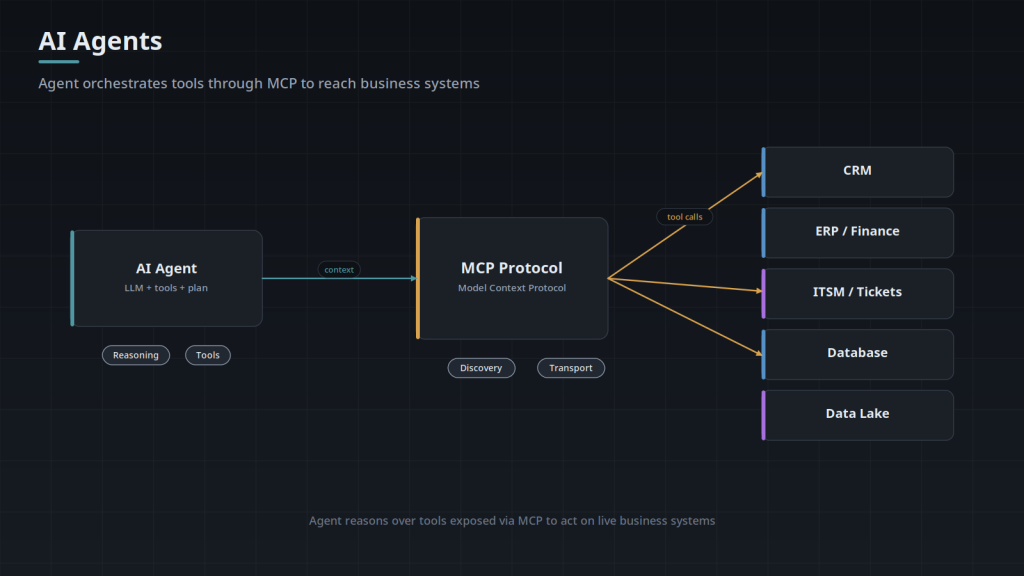
The Model Context Protocol is a JSON-RPC 2.0 protocol between a host application and servers that expose tools the model can call, resources it can read, and prompts a user can invoke. The practical consequence for an integration project is that the tool definition lives in the server rather than in the agent, so one connector to your ticketing system serves any client that speaks the protocol, and replacing the model does not mean rewriting the connector.
Servers run over one of two transports. A stdio server runs as a local subprocess and inherits the environment and credentials of whatever launched it, which is convenient on one workstation and wrong for anything shared. A remote server over streamable HTTP has its own authorization boundary and can enforce per-user scopes on each call. Anything more than one person uses ends up remote, so it is worth building for that from the start rather than porting later.
The cost that gets underestimated is context. Every tool definition in scope is sent to the model on every request, so connecting a dozen servers with dozens of tools each can spend thousands of tokens before the user has typed anything, and selection accuracy falls as the list grows. Restricting a deployment to the specific tools its workflow uses does more for reliability than any instruction telling the model which tool to prefer.
Content returned by a server is untrusted input, not instruction. A document, a ticket comment, or a web page retrieved through a tool can contain text addressed to the model, and an agent with write access that follows it will act on behalf of whoever wrote that text. The defenses are structural: keep the permission scope narrow enough that a compromised instruction cannot do much, and put approval gates on the actions where it could.
What an Evaluation Suite Actually Contains
A case is an input, a fixed starting state, and an assertion about what is true afterward. Assertions on the final state of the system are worth more than assertions on the text, because two differently worded answers can both be correct while only one of them created the right record. Where the output is the deliverable, such as a drafted reply, the assertion has to be about specific required content rather than overall quality.
Grading splits into two kinds. Deterministic checks ask whether a record exists with these field values, whether a given tool was called with given arguments, or whether no write occurred at all. Model-graded checks handle open text and are useful, but their scores move when the grading model moves, so they belong to trend watching rather than to a pass or fail gate.
Pin explicit model versions rather than floating aliases, because an alias moves to a new snapshot and behavior changes with no commit on your side. Run each case more than once as well. Agent behavior is not deterministic even at temperature zero, since tool results, timestamps, and retrieval order vary between runs, so a case that passes once and fails once is a finding rather than noise.
Draw the cases from real traffic: closed tickets, past requests, documents that were actually processed. A suite written from the specification only tests the specification. Alongside the ordinary cases, four types are worth writing deliberately because they cover the behavior that a good day never exercises.
- The ambiguous request, where correct behavior is a clarifying question rather than an answer. The assertion is that no write occurred and a question was asked.
- The out-of-scope request, where correct behavior is a handoff. These are what catch scope creep introduced by later prompt edits.
- The unreachable-system run, executed with the tool endpoint blocked or returning 503. The pass condition is the absence of an answer plus a surfaced tool error in the transcript, which is what distinguishes a genuine refusal from the agent happening to produce the right answer from context it already had.
- The near-duplicate pair, two inputs differing in exactly one significant field such as account, date, or amount. These catch an agent that is keying off the wrong part of the request and getting away with it on typical inputs.
Diagnosing a Change in Agent Behavior
The recurring operational question is not whether the agent is broken but why it is behaving differently than it did last week. Five things change underneath it: the prompt, the model, the retrieval corpus, the tool layer, and the data in the source systems. Only two of those are under your version control, which is why the other three account for most of the surprises.
This is a logging problem before it is an analysis problem. Three fields decide whether the question is answerable in minutes or not at all: the exact model identifier the provider returned rather than the one requested, a hash of the assembled system prompt, and the list of tools that were in scope for that run. Record those per run alongside the tool calls and arguments, and the causes separate quickly in the logs. The signatures below are what tells them apart.
- Same input, same reasoning, wrong action taken: the tool layer changed. Compare the arguments in the transcript against the target API's current schema, since a renamed or newly required field shows up first as an error the agent worked around.
- Same input, different answers on the same day: retrieval, not the model. Diff the retrieved document identifiers between the two runs before touching anything else.
- Behavior shifted on a specific date with no deployment on your side: a floating alias, a provider snapshot update, or a fallback to a different model under rate limiting. The recorded model identifier settles this in one query.
- Failures clustered on one user or one department: permissions, not capability. The agent is seeing a smaller record set than the case was written against, and the answer looks confident because nothing reported an error.
- Degradation that worsens as a session runs longer: context accumulation. Transcript length at the point of failure correlates, and the fix is a truncation and summarization policy rather than prompt wording.
Frequently Asked Questions
How is an agent different from RPA or a workflow automation tool?
The difference is where the decision lives. An RPA script or a workflow rule encodes the branching at build time: if this field says X, do Y. An agent decides at run time which tool to call based on the request and on what earlier calls returned, which is what lets it handle inputs nobody enumerated, and also what makes verifying it a testing problem rather than a code review problem. Where the branching is genuinely fixed and small, a rules engine or a scheduled job is cheaper to operate and easier to certify, and it is the better answer.
One of our systems has no API. It produces a nightly export and accepts an upload. Can an agent work with it?
Yes, but the constraint changes the design rather than being absorbed by it. Reads come from the last export, so every answer carries a staleness bound that has to be stated to the user and enforced in the prompt, and any decision that depends on same-day data has to be routed to a person or to another system. Writes become an entry in a file the system ingests on its own schedule, which means the agent cannot confirm the write landed inside the conversation; it can only confirm the item was queued, and a separate reconciliation step has to check the next export for the record and raise it when it is missing. That reconciliation loop is the real work in this pattern, and it is why systems like this usually start read-only.
Can an agent run entirely inside our environment?
Documents, logs, and tool traffic can be kept inside your network; the variable is where inference happens. The options are a model hosted in your own cloud tenant, a provider endpoint that sits inside your cloud vendor's boundary, or an open-weights model on hardware you control, and they differ in which models you can use, what the hardware costs to run, and how quickly you get access to newer versions. Open-weights models generally lag the hosted ones on long multi-step tool use in particular, which is the capability agents lean on hardest, so the gap should be measured on your own test set rather than assumed in either direction.
How does integration actually proceed, and what takes the time?
System by system, and the time goes into access rather than code. For each system the steps are the same: register an application, get the requested scopes approved, connect with read scopes only and confirm the agent retrieves the right records for real requests, then enable write calls behind an approval gate. Adding systems one at a time keeps a failure attributable, because each additional tool multiplies the paths a run can take. The dependency that sets the pace is the person who can approve the registration and grant scopes in each system, and that person usually does not report to whoever owns the project.
What do we have to decide, as opposed to supply?
Four decisions shape everything downstream: which actions require human approval and who is authorized to give it, what the agent should do when it cannot complete a task, how long prompts and tool results are retained and who is allowed to read them, and whether the agent acts as the requesting user or as a service identity. These are policy questions rather than technical ones, and none of them can be deferred, because each changes the architecture. The approval question in particular determines whether the workflow needs durable state, since a run that waits on a human cannot be held in memory.
Are we locked into one model provider?
The parts that carry the work port cleanly, and the call sites do not. Tool definitions, retrieval, evaluation cases, and approval logic all sit outside the model and move unchanged, and an MCP server is provider-neutral by design. What does not port is the layer that talks to the API: tool-call formats, structured-output modes, system-prompt handling, and reasoning controls all differ, so the integration code is rewritten even when the tools are not. Prompts also need retuning rather than copying, and that is usually the larger share of the work in a switch.
What do we have to supply for the evaluation suite?
You supply the cases and the person who settles arguments about them. The cases come out of your own history, and each one needs the record of what the correct outcome actually was, which is often the part that no longer exists in writing. Somebody on your side has to be able to say that a given output is right or wrong, and to arbitrate when two of your own reviewers disagree, because without that the suite cannot gate anything. Expect a share of the cases to have no agreed answer at all; when your staff handle the same request three different ways, that is a finding about the workflow and has to be settled before an agent can be held to it.
Recorded Demonstrations
A recorded example of an agent operating a real industrial system rather than a chat transcript, over an MCP server.